Web DevelopmentInfrastructureProduction ReadinessApprox. 5 min read
Published 13 Oct 2026 · By Mario J, Core Dynamics
Building an app or website has never been more accessible. AI coding tools, modern frameworks, and hosted platforms let a founder turn an idea into a working interface in days. A prototype that once needed a team can now be created by one person.
That changes where the hard part begins. A working demo proves that an idea can be built. It does not prove that customers can rely on it, that their data is protected, or that the business can support it when usage grows.
The new gap: getting software to exist is easier. Getting it ready to serve real users is still engineering work.
A prototype is designed to answer “does this idea work?” Production software must answer harder questions every day: can users sign in safely, can the system recover when a dependency fails, can the team find the cause of a slow request, and can changes be released without taking the service down?
Those questions often surface after the first version has already attracted users. The app may have no dependable backups, unclear access controls, fragile deployments, missing alerts, or a database that was never designed for real traffic. Fixing these foundations later can cost more than addressing them before launch.
This is true whether the first version was written by an experienced team, generated with AI, assembled from a no-code tool, or delivered by an agency. The tool used to build it does not remove the need to operate it.
What production-ready means
Production readiness is not a single deployment button. It is a set of practices that makes software safe to change and dependable to use:
Reliable application engineering: clear architecture, maintainable code, useful automated tests, and sound handling of errors and edge cases.
Security and data protection: appropriate authentication, access controls, secure secrets, dependency updates, and careful handling of personal data.
Operational infrastructure: repeatable environments, deployment automation, backups, monitoring, alerting, and a recovery plan.
Ownership after launch: documentation, clear responsibilities, and a practical way to respond to incidents and improve the product.
Production readiness brings quality checks, security, monitoring, and recovery planning together around the application.
The right level of readiness depends on the product. A small public landing page does not need the same controls as a payments platform. The goal is to understand the risks and build the safeguards that fit.
Human validation and local markets
AI can produce a convincing interface and pass the tests it was asked to run. That still does not tell you whether the product makes sense to the people who will use it. Real users and experienced reviewers need to validate the complete product: important journeys, confusing states, accessibility, the accuracy and tone of AI-generated responses, and what happens when the system is uncertain or wrong.
Product validation brings the people building a product together with the people who will use it.
Human involvement is also part of the operating design in some contexts. In the EU, the AI Act requires high-risk AI systems to be designed for effective oversight by natural persons. GDPR can also give people rights that include human intervention when certain decisions with legal or similarly significant effects are based solely on automated processing. These obligations depend on the system, purpose, and applicable rules; they do not mean every AI feature requires the same review process. See the EU AI Act, Article 14 and GDPR, Article 22.
That oversight must work in practice. Teams may need clear approval points, a way to challenge or override an AI output, useful explanations, escalation paths, and records showing what happened. A policy written on paper is not enough if operators cannot understand the output or intervene in time.
A product also needs to feel native in each market it serves. Localization goes beyond translating strings: it can involve language and tone, date and number formats, payment expectations, accessibility, support workflows, and local product or regulatory requirements. A flow that feels obvious to one audience can confuse another.
Core Dynamics offers full product validation with real human review, from end-to-end journey testing to AI output and operational checks, as well as localization for different markets. We help teams adapt the product experience and its human review process to the users and jurisdictions they plan to serve.
How to close the gap
Teams do not always need to start over. A focused review can identify what is already sound, what could fail under real use, and which changes should happen before launch. From there, the work might mean strengthening an existing app, rebuilding one fragile feature, or defining a managed infrastructure setup for the product.
Core Dynamics helps teams move through that gap with three connected services: custom web and application development for products that need a stronger foundation; AI agent pipeline design and integration for teams automating real workflows; and infrastructure engineering for deployment, monitoring, reliability, and ongoing operations.
We start with the software you have and the outcome you need. Then we make the production path concrete: what needs to change, how success will be checked, and who will own the system once real users depend on it.
The New Engineering Operating Model: Humans Direct, Agents Execute
AI EngineeringSoftware FactoriesOperating ModelApprox. 10 min read
Published 20 Sep 2026 · By Adam C, Core Dynamics
AI coding agents change more than the speed of implementation. Once an agent can inspect a repository, plan a change, write code, run tests, respond to review comments, and prepare a release, the old assumption that engineering work moves from person to person stops being useful.
The scarce resource is no longer the ability to produce another draft of the code. It is the ability to define the right problem, provide reliable context, set decision boundaries, evaluate evidence, and accept responsibility for the result.
That leads to a different operating model: humans direct the system and remain accountable for outcomes; agents execute bounded work and return evidence. The goal is not a lights-out engineering department. It is a software factory in which autonomy is deliberate, observable, and reversible.
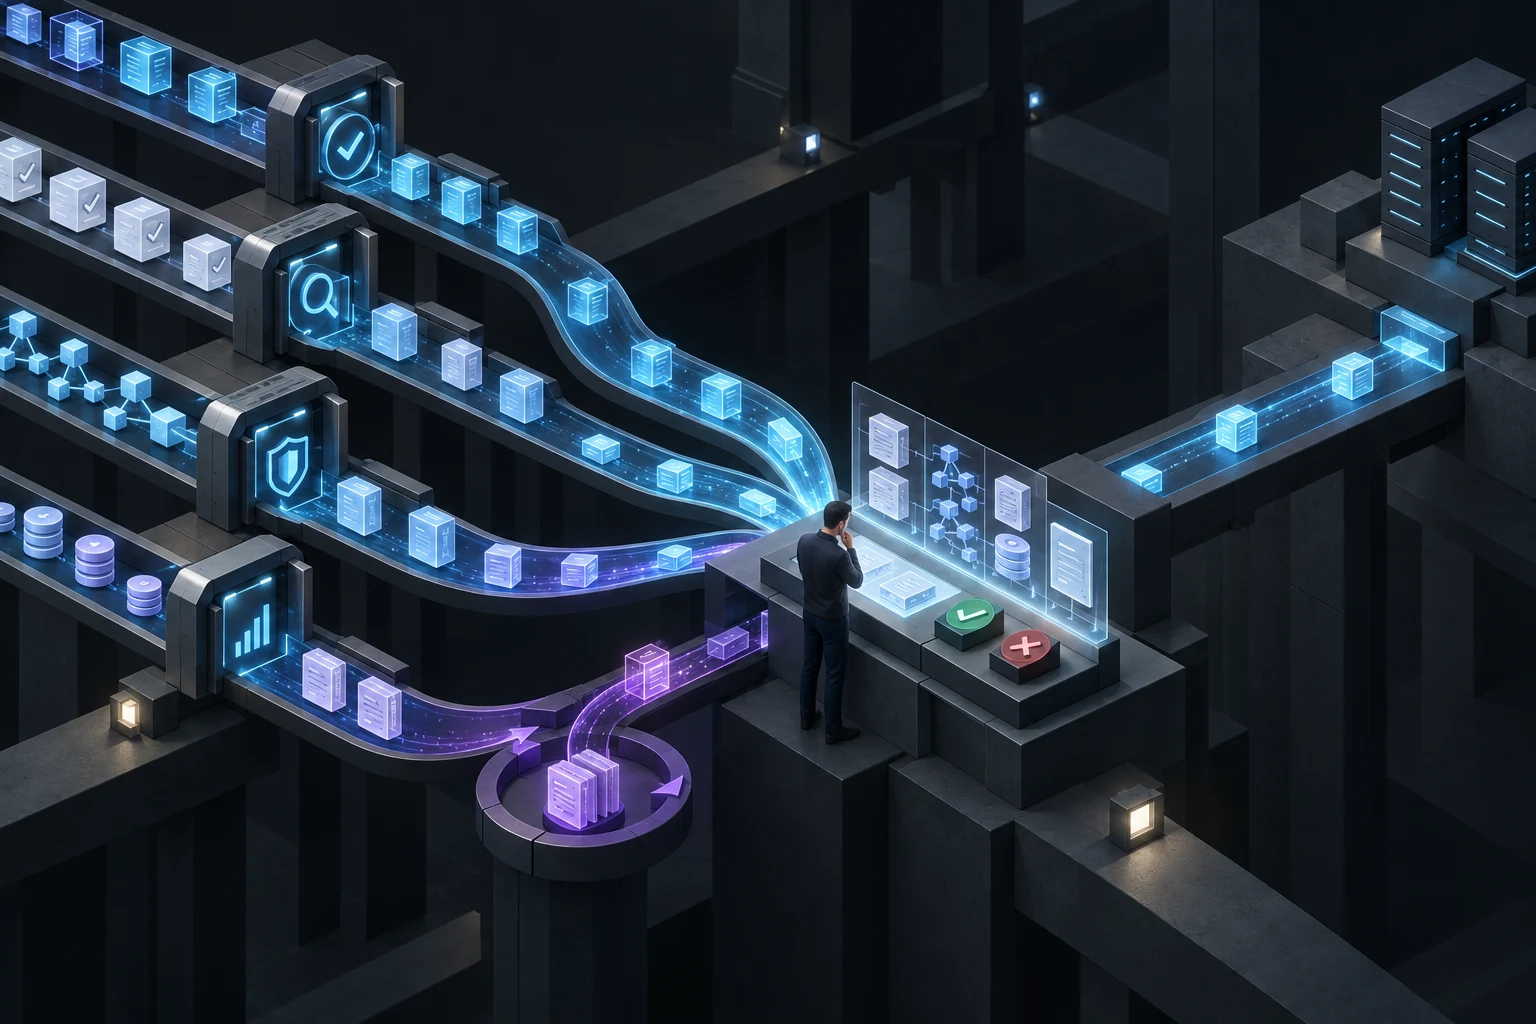
Specialized agent stages connect through a shared orchestration layer; engineers define the intent, constraints, context, and conditions for a safe release.
The operating principle: give agents ownership of well-defined, reversible execution. Keep humans accountable for intent, architecture, exceptions, and consequential decisions.
Traditional delivery is organised around human activity: write the ticket, implement the change, review the pull request, run the release. An agentic team is better organised around a controlled work package. That package combines an outcome, relevant context, constraints, acceptance tests, permissions, and an escalation path.
This distinction matters. A vague instruction such as “improve checkout” forces an agent to invent product intent. A strong work package states which user journey is failing, which services may change, which security and latency limits apply, how success will be tested, and which decisions require approval.
The work package becomes the contract between human judgment and machine execution. Better models help, but the quality of this contract often determines whether the result is production-ready or merely plausible.
Seven roles in an agentic delivery loop
These are decision roles, not necessarily seven job titles. In a small team, one person may hold several human roles. In a larger software factory, each agent role may be a coordinated pool of specialised workers.
1. Product lead: defines the outcome
The product lead describes the user or business result, the acceptable risk, and the evidence required for acceptance. They should avoid prescribing code-level implementation unless the implementation itself is a constraint.
2. Architect: defines the boundaries
The architect turns intent into system constraints: service boundaries, interfaces, data ownership, non-functional requirements, and decisions that agents may not make alone. Architecture becomes less about drawing a static target state and more about defining a safe decision space.
3. Context engineer: prepares the environment
The context engineer assembles the repository state, design rules, prior decisions, tool access, test fixtures, and operational knowledge needed for the task. This role prevents every agent run from rediscovering the organisation through trial and error.
4. Planner agent: decomposes the work
The planner proposes tasks, dependencies, assumptions, and checkpoints. Its plan is inspectable before expensive or high-impact execution begins. When uncertainty is material, it routes a question back to a human instead of hiding the assumption inside generated code.
5. Builder agents: produce the artifacts
Builder agents implement code, tests, migrations, documentation, and configuration in isolated workspaces. Several can work in parallel when their contracts are clear and their changes can be integrated safely.
6. Reviewer agents: challenge the result
Reviewer agents should be separated from the builders they evaluate. They inspect diffs, exercise edge cases, scan for security and policy violations, and compare the result with acceptance criteria. Their job is not to agree; it is to find credible reasons the change should not ship.
7. Human reviewer and platform operator: decide and observe
A human reviews the evidence at the appropriate control point, concentrating on ambiguity, trade-offs, and impact rather than rereading every generated line. The platform operator then releases within policy, watches production signals, and feeds what happened back into the next work package.
How the roles work in sequence
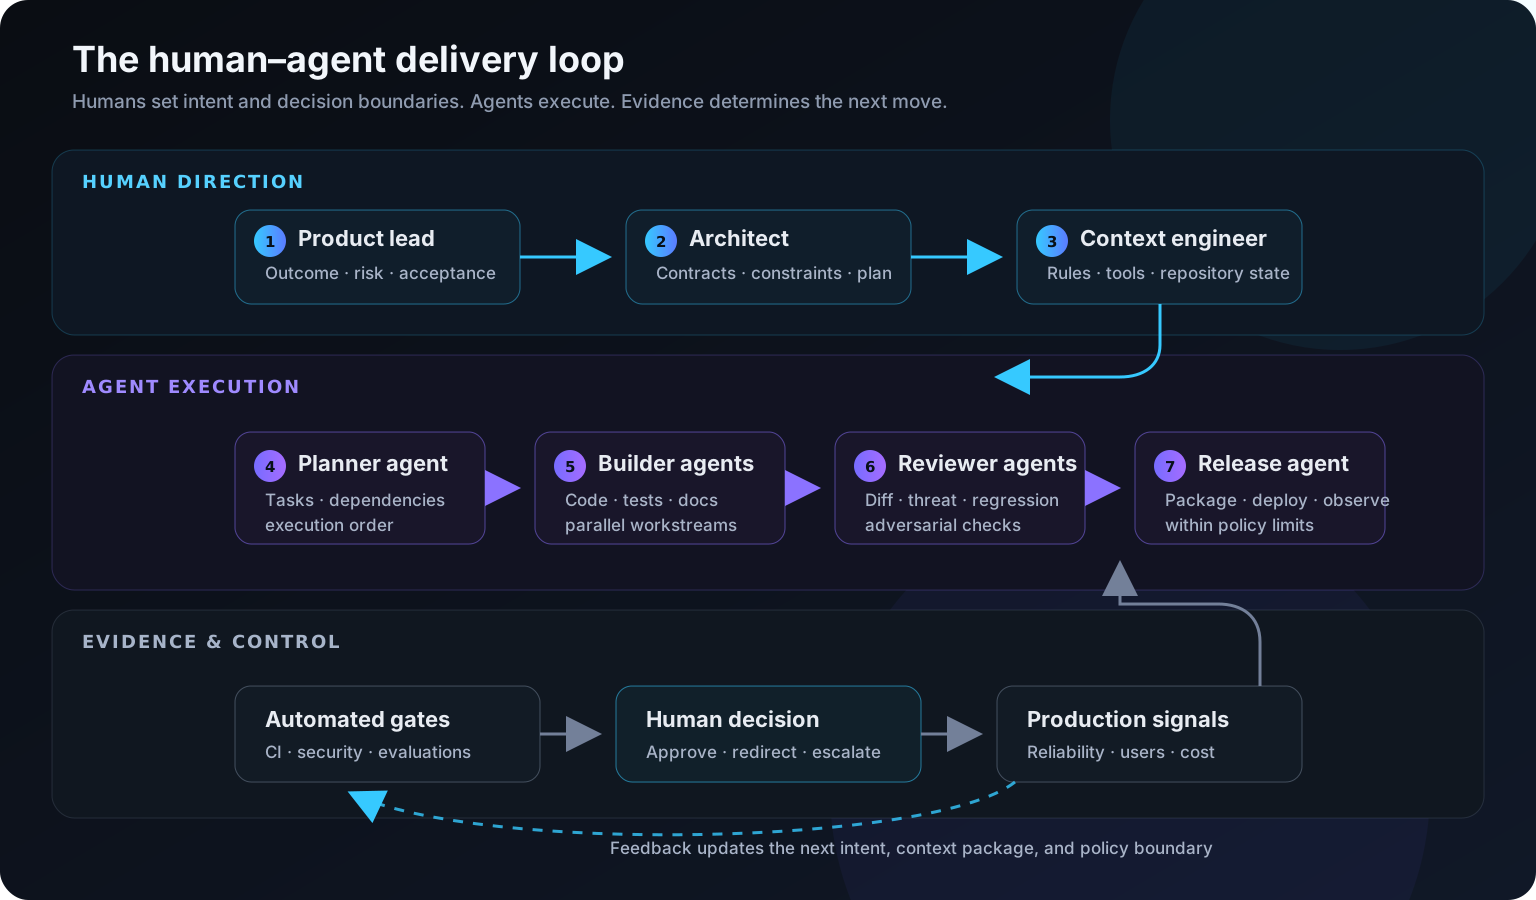
The sequence is not a one-way assembly line. Human direction moves into agent execution; automated and human controls evaluate the result; production evidence returns to the next planning cycle. A mature team makes every transition explicit.
The operating loop separates three concerns: humans define the decision space, agents execute within it, and evidence controls whether work advances, loops back, or escalates.
Notice that approval is not placed after every agent action. That would preserve the cost of the old workflow while adding automation overhead. Controls should sit where the risk changes: before privileged access, before an irreversible migration, before exposure to customers, or when evidence falls outside an agreed threshold.
What agents can own—and what humans must own
The cleanest division is based on reversibility, observability, and consequence—not on whether a task looks technical.
Agents can own
Planning within an approved architecture and scope
Routine implementation in isolated branches or workspaces
Test generation, static analysis, and documentation updates
Low-risk refactors with strong regression coverage
Reversible deployments inside defined policy limits
Monitoring, evidence collection, and rollback recommendations
Humans must own
Product intent and prioritisation
Architectural trade-offs with long-term consequences
Changes to security, privacy, or compliance boundaries
Ambiguous requirements and conflicting stakeholder needs
Irreversible data operations and high-blast-radius releases
Exceptions where policy and evidence disagree
Autonomy scales when approval is based on visible evidence. Humans should handle exceptions and consequential choices, while repeatable controls run continuously.
A useful test: if a decision is hard to reverse, difficult to observe, or capable of crossing a trust boundary, keep a human accountable for it.
How to redesign team workflows
Adding agents to the existing ticket queue is not an operating-model change. It often creates more pull requests, more review pressure, and faster production of poorly framed work. Teams need to redesign the flow around context and evidence.
Start with one bounded workflow. Choose a repeatable change class with good tests, limited permissions, and a clear rollback path.
Define the work-package contract. Standardise how outcomes, constraints, context, acceptance criteria, tools, and escalation rules are supplied.
Separate builders from evaluators. Use independent review agents and deterministic checks rather than asking the producing agent whether its own work is correct.
Place approval at risk boundaries. Require human decisions where authority, blast radius, data sensitivity, or uncertainty increases.
Make production part of the loop. Feed incidents, support signals, performance changes, and rollback data into planning—not just into an operations dashboard.
Expand autonomy only after evidence improves. Broaden permissions and task scope when the workflow demonstrates reliability, not when a demo looks impressive.
How to measure the operating model
Lines of generated code and agent utilisation are activity metrics. They do not tell you whether the software factory is producing better outcomes. Measure the whole system instead.
Flow: lead time from accepted intent to production, queue time, and percentage of work completed without avoidable handoffs.
Control: automated-check coverage, human review latency, escalation rate, policy violations, and unauthorised-action attempts.
Economics: total engineering and compute cost per accepted change, including rework and review.
Learning: how often production evidence improves a rule, test, context package, or architectural decision record.
The best operating model does not maximise autonomous activity. It maximises useful change while keeping failures contained and decisions accountable.
Final point
Engineering teams will not become irrelevant as agents become more capable. Their work moves toward the decisions that machines cannot responsibly own: what matters, what the system must protect, which trade-offs are acceptable, and when the evidence is strong enough to proceed.
The companies that benefit most will not be those that simply deploy the largest number of coding agents. They will be the ones that build a clear operating system around them—one where context is maintained, authority is bounded, evidence is visible, and a human remains accountable when the answer is not obvious.
Previous Article
23 Apr 2026
LangChain vs. LangGraph
AI EngineeringLangChainLangGraphApprox. 7 min read
Published 23 Apr 2026 · By Adam C, Core Dynamics
When teams ask us whether they should use LangChain or LangGraph, the real question is usually about control. Do they need a straightforward sequence of model and tool calls, or do they need a stateful execution graph with loops, branches, and recovery paths?
LangChain is excellent when the workflow is mostly linear and can be expressed as a pipeline of steps. LangGraph becomes valuable when the system needs durable, multi-step agent behavior where state and transitions must be explicit.
In practice, this is not an either-or religion. Many production stacks use both. LangChain handles reusable components and tool abstractions, while LangGraph coordinates how those components execute over time.
Quick summary: Use LangChain to build capabilities. Use LangGraph to orchestrate complex agent behavior with explicit state transitions.
The key difference is execution model. LangChain is centered on chains and composable building blocks. LangGraph is centered on state machines represented as graphs.
In LangChain-first flows, execution typically moves forward step by step. In LangGraph-first flows, execution can loop, branch, pause, and resume based on state updates and node outcomes.
That difference matters in reliability work. If you need deterministic checkpoints, retries at node level, human-in-the-loop approval gates, or long-lived agent sessions, graph orchestration usually gives clearer control.
Where LangChain works best
Fast capability assembly
LangChain is great for quickly assembling prompts, retrievers, tools, and output parsers into a usable workflow. It gives teams a broad set of integrations and abstractions to move from prototype to useful internal tooling quickly.
Composable, readable pipelines
For many business workflows, a clean pipeline is exactly enough. Think classify intent, retrieve context, call model, format output. LangChain keeps this understandable and easy to evolve.
Strong fit for MVP-to-v1
If the system does not need persistent graph state, LangChain usually keeps complexity lower and delivery speed higher.
Where LangGraph works best
Stateful agent orchestration
LangGraph is designed for scenarios where the agent must track state across multiple steps and choose transitions dynamically. That includes retry loops, tool fallback policies, and conditional routing after validation.
Durable, controllable execution
When correctness matters more than raw speed, explicit graph nodes and edges make behavior easier to inspect and reason about. It also helps isolate failures to specific transitions.
Multi-actor or supervised workflows
If you need planner-executor patterns, handoffs, or human approvals in the middle of execution, LangGraph maps naturally to that architecture.
Practical rule: The more your system resembles a workflow engine, the more LangGraph tends to be the right control layer.
Framework graphs
Two quick visual references for each framework architecture shape:
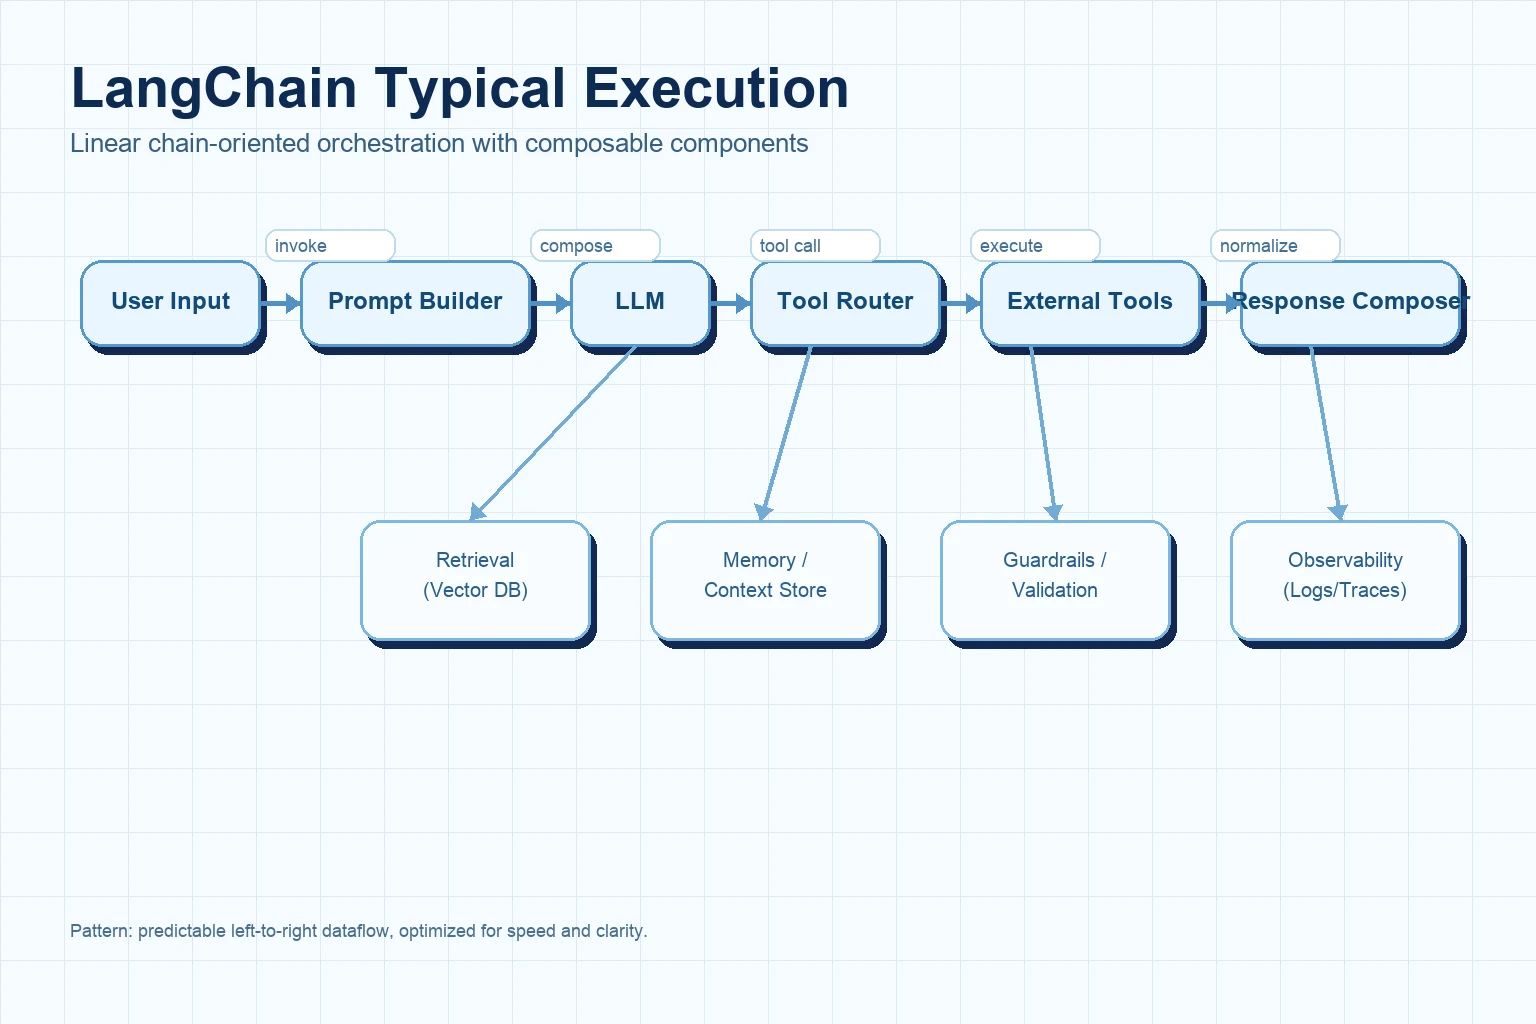
Graph 1: LangChain flow (chain-oriented)
LangChain usually fits flows that look like a directed pipeline: compose prompt and tools, call model, execute tools, return output.
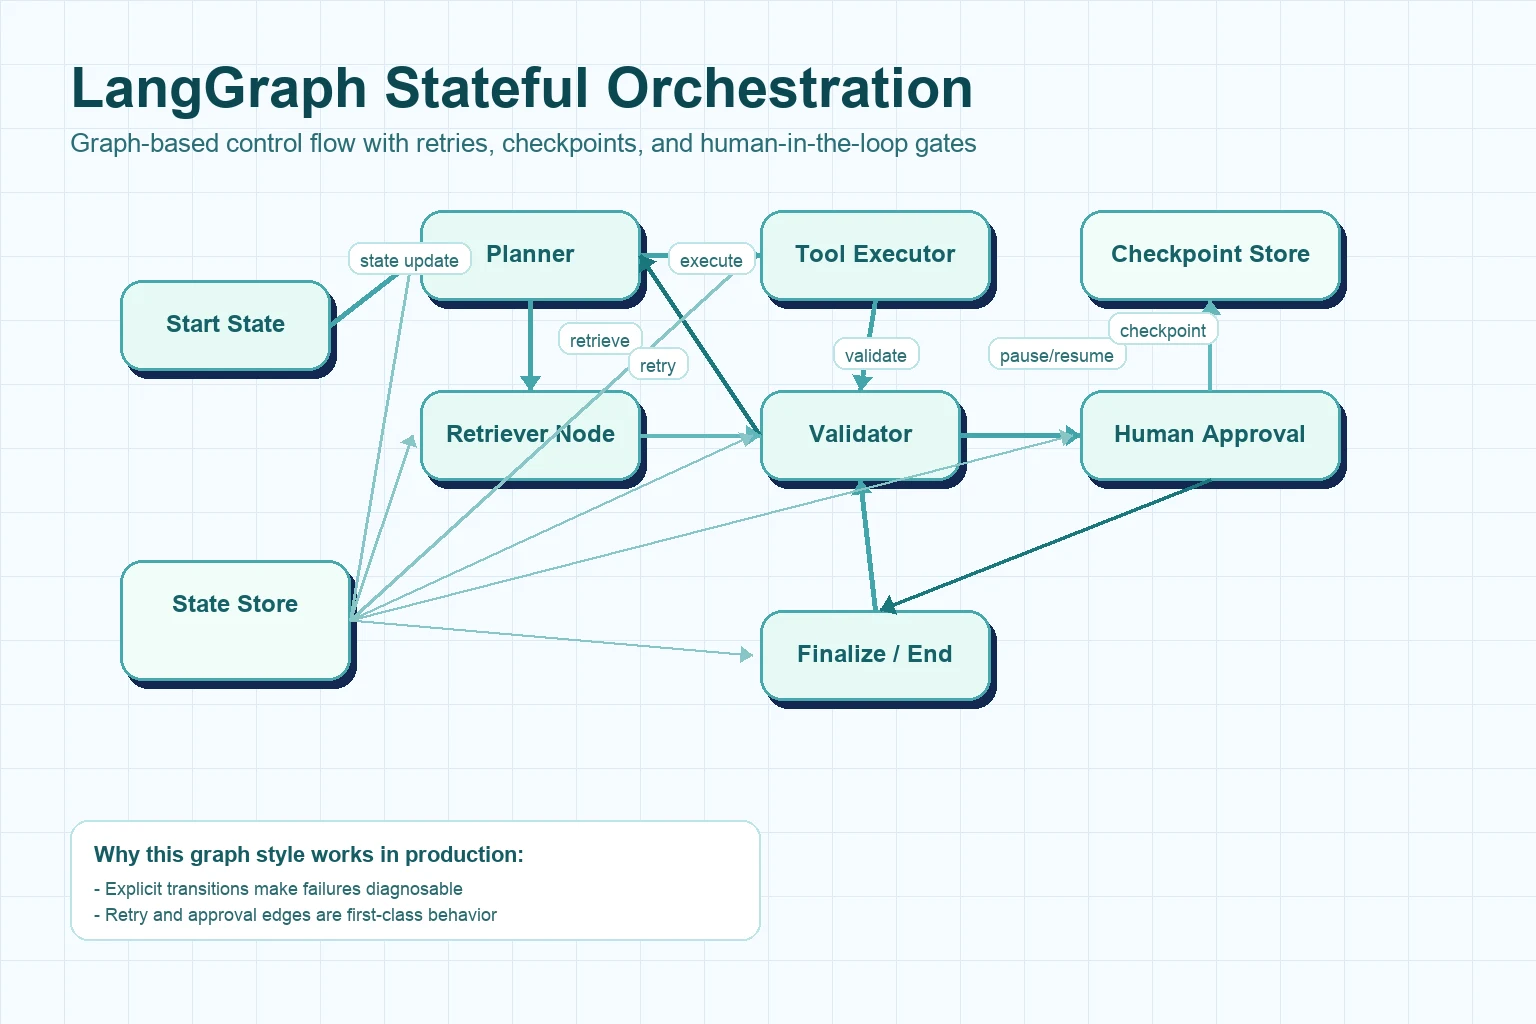
LangGraph models execution as explicit state transitions, which makes loops, retries, checkpoints, and human handoffs first-class architecture elements.
Selection guide for teams
Choose LangChain first if the workflow is mostly linear and your priority is fast delivery with clean abstraction layers.
Choose LangGraph first if the workflow needs branching, retries, durable state, and explicit orchestration control.
Use both together when you want LangChain components inside a LangGraph-controlled runtime for production reliability.
The architecture decision is less about popularity and more about failure modes. If failure handling is simple, chains are usually enough. If failure handling is part of the product behavior, graph orchestration usually pays off quickly.
Final point
LangChain and LangGraph are complementary, not competing religions. The cleanest production systems often treat them as layers: LangChain for capabilities, LangGraph for execution control.
If your team is deciding this week, start by mapping your real runtime behavior. Count branches, retries, approvals, and state transitions. That architecture map will usually tell you which framework should sit at the center.
Previous Article
22 Mar 2026
MCP server architecture basics
ArchitectureMCPAgent SystemsApprox. 8 min read
Published 22 Mar 2026 · By Adam C, Core Dynamics
At Core Dynamics, clients almost never start by saying, "We need MCP." They usually say something more direct: "We want the assistant to read our systems, maybe write later, and we need to know it will not break anything." That is the real brief. By the time teams call us, they are usually done with flashy demos. They want control.
We have been in kickoff calls where the first notes on the whiteboard were not speed or model choice. They were simpler than that. Who can call what? What gets logged? What happens when a backend fails? That is where good MCP architecture starts.
Model Context Protocol, or MCP, gives AI clients a standard way to find tools, call them, and exchange structured context with external systems. In plain terms, an MCP server is the controlled middle layer between an AI client and the systems a business actually runs on: APIs, databases, workflows, documents, and internal services.
The pattern is pretty consistent. Clients want read access before write access. They want a short list of solid tools before a giant catalog. And they want every call to be easy to trace. So for engineers, the job is to expose useful capability without exposing chaos. For everyone else, the simple version is this: the MCP server is the doorway, the guardrail, and the record of what happened.
An MCP server sits between an AI client and one or more backend systems. The client might be a desktop assistant, a browser agent, an internal ops console, or another service. The server publishes tools and schemas. The client discovers those tools, sends structured calls, and gets structured responses back.
Here is the plain-English version. If a chatbot needs to look up a customer invoice, it should not talk straight to the accounting database. It should talk to an MCP server instead. The server exposes a tool like get_invoice(invoice_id), checks the input, applies access rules, calls the right backend, and returns only what the client is allowed to see.
Non-technical summary: The MCP server is the translator and gatekeeper between an AI system and the software it needs to use. It makes the interaction consistent and much safer.
The core architectural layers
A solid MCP server usually has five layers. Early prototypes often mash them together, and that is fine for a week or two. But once real users show up, the separation matters.
1. Transport layer
This is the front door. It handles incoming MCP requests, stream mechanics, content types, and response framing. It should not hold business logic. Its job is to translate protocol traffic into internal application calls.
2. Tool registry and schemas
This layer defines what tools exist, what they are called, what arguments they accept, and what shape they return. Tight schemas matter. Models behave better when the contract is narrow and clear instead of vague and open-ended.
3. Orchestration layer
This is where routing, retries, policy checks, and cross-service composition happen. One tool might call a single backend. Another might touch three systems and stitch the answer together. This layer is where most of the real design work lives.
4. Integration adapters
Adapters connect the server to databases, CRM APIs, file stores, search indexes, or internal services. Keeping them separate stops protocol logic from getting tangled up with vendor SDK code.
5. Observability and policy controls
Production MCP servers need logs, traces, error handling, rate limits, and auth checks. If an AI client can call a tool, you should be able to answer a few basic questions fast: who called it, what they passed in, which system it touched, and what came back.
Practical takeaway: A lot of early MCP builds stop at schemas and tool names. That works right up until the first bad input, permission bug, or backend timeout.
What happens during a request
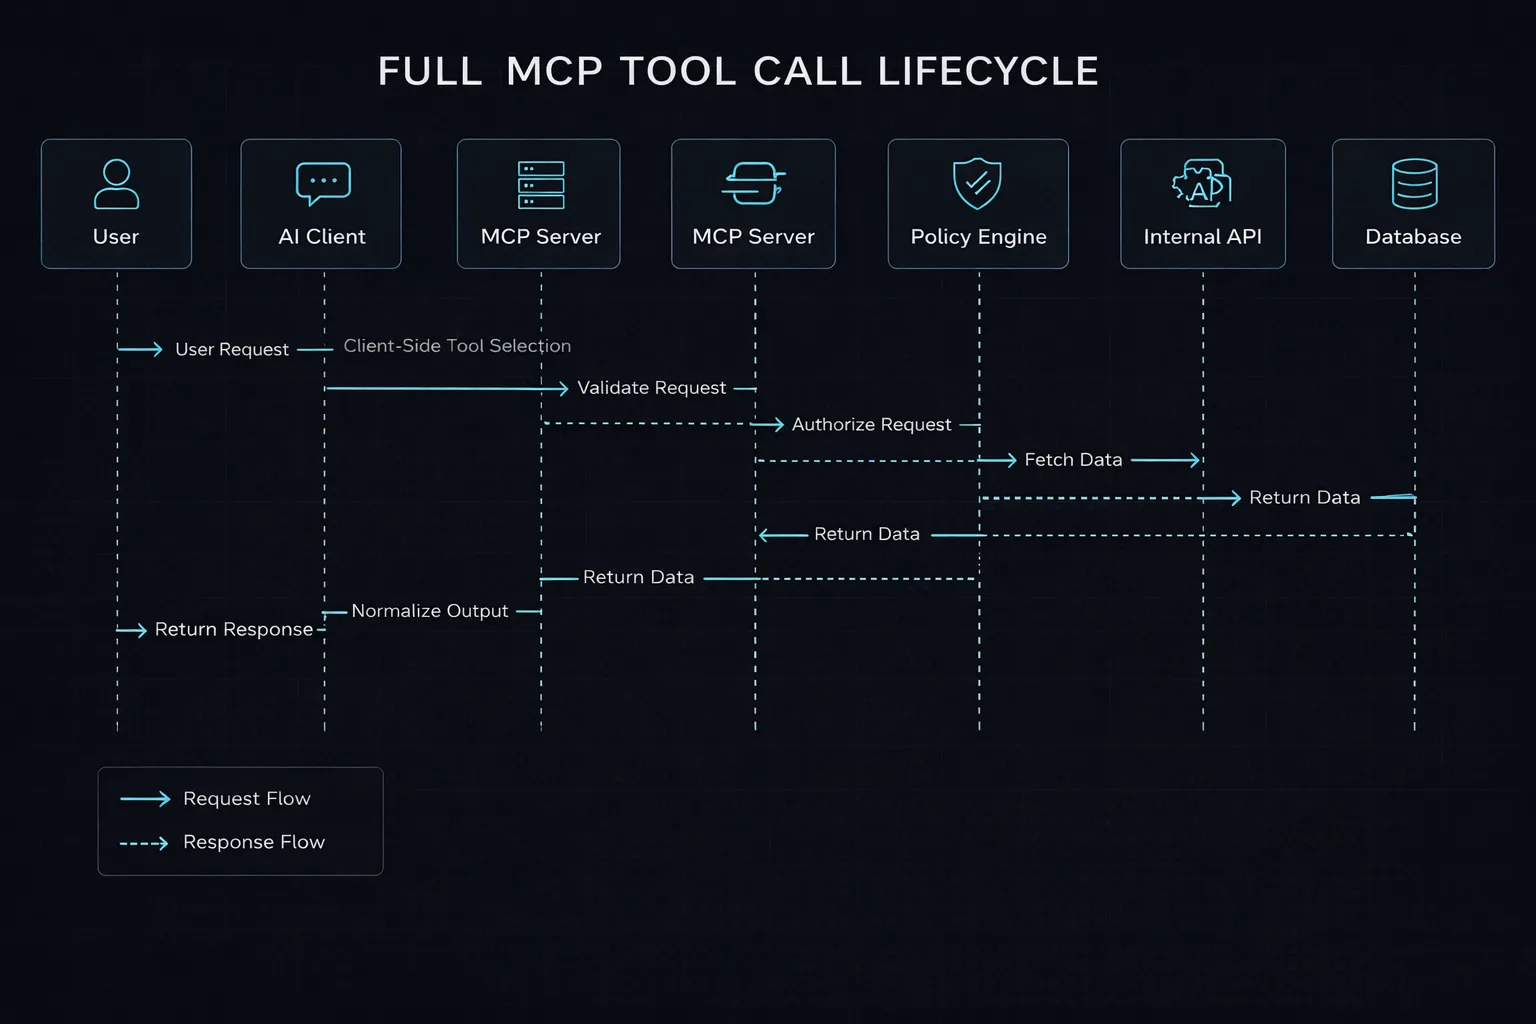
The easiest way to understand MCP is to follow one request from start to finish.
Discovery: the client learns which tools the server exposes and what input schema each tool expects.
Selection: the language model decides that a tool is needed for the current task.
Invocation: the client sends a structured tool call to the MCP server.
Validation: the server verifies required fields, types, size limits, and policy constraints.
Execution: the orchestration layer invokes the relevant adapter or internal service.
Normalization: raw backend output is transformed into a predictable, model-friendly response.
Return: the client receives the result and uses it in the next reasoning step.
Here is the thing: an MCP server is not just an API wrapper. It is the layer that turns a fuzzy model decision into a clean, deterministic action. If that layer is weak, the whole system gets weird fast.
That is also why "the AI has access to our systems" is the wrong mental model. What matters is that the AI has access only through a small set of server-defined operations, each with a tight contract and a traceable path.
Security and trust boundaries
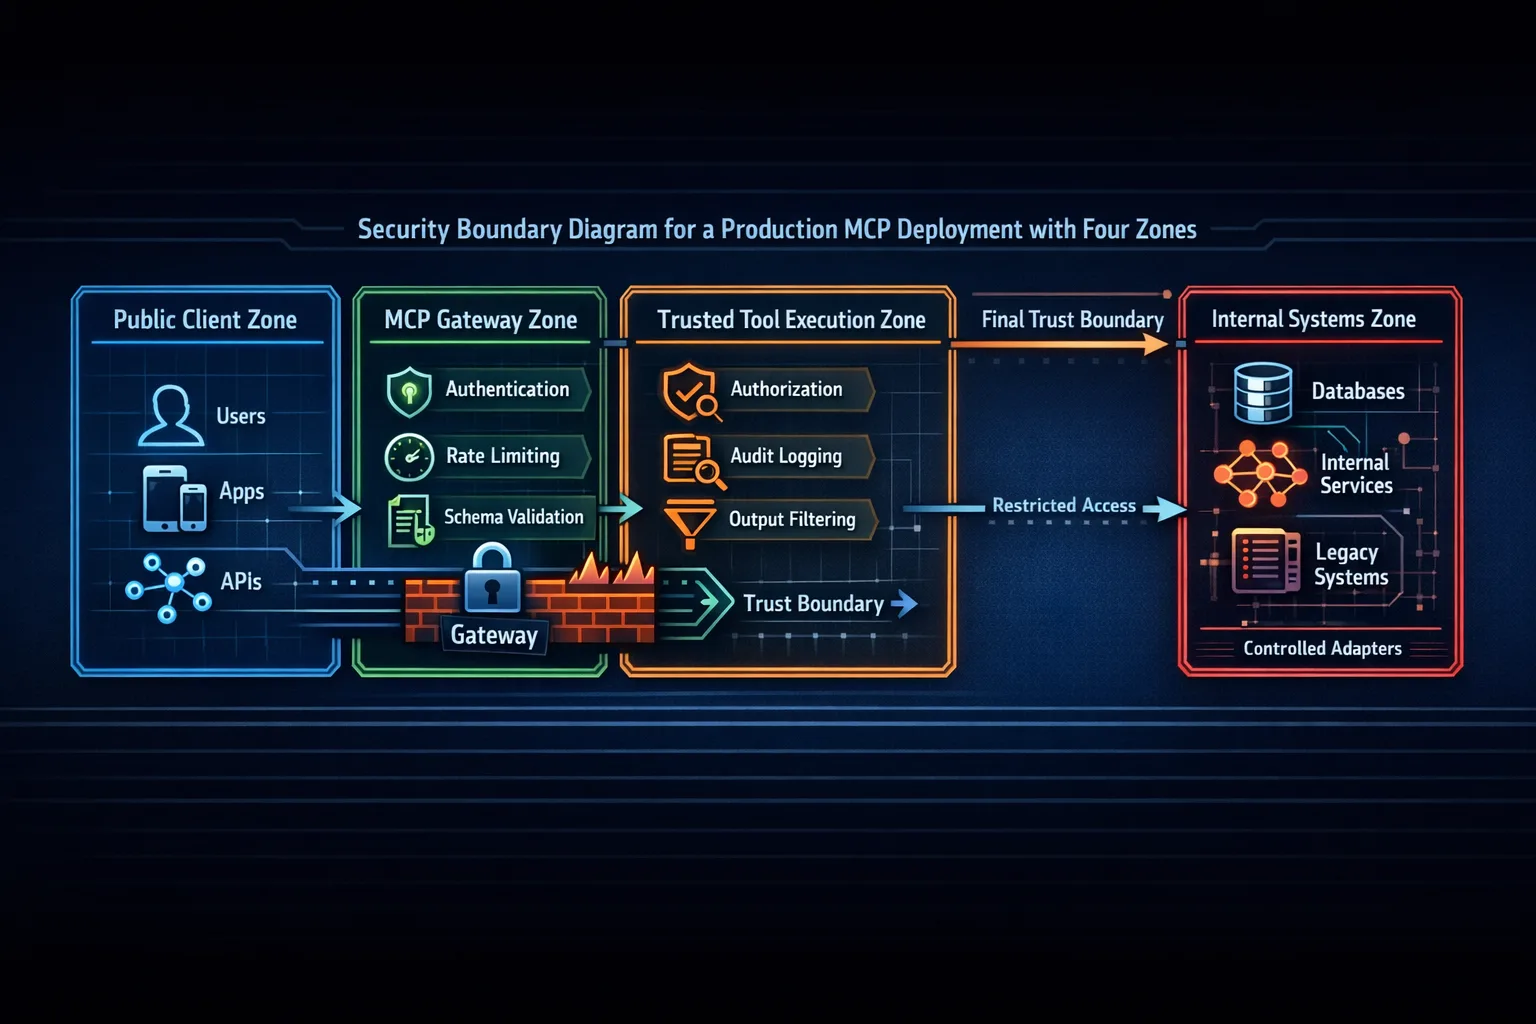
Most MCP architecture mistakes are really trust-boundary mistakes. Teams assume the model will behave if the tool descriptions are clear enough. That is not a security plan. The server should act as if every call could be malformed, too broad, replayed, or made by a client with the wrong permissions.
At a minimum, the server should enforce authentication, authorization, input validation, output filtering, and rate limits. Sensitive tools should sit in tighter lanes. A read-only lookup tool should not live in the same trust tier as a write action that can change records, trigger payments, or open tickets.
We also see teams return too much data because it feels convenient. But convenience is not the goal. If a billing tool needs only invoice status and due date, it should not also return payment history, internal notes, and account IDs unless those fields are clearly required.
Non-technical summary: The risk is not that the AI suddenly turns evil. The risk is that a badly designed server gives it too much authority or too much data for the job at hand.
Patterns that matter in production
Once a prototype touches real users, three patterns matter almost every time.
Thin tools, thick policies
Keep tool interfaces simple, but make policy enforcement deep. A tool should feel easy to call, while the server quietly handles validation, auth checks, idempotency, and backend-specific safeguards.
Stable contracts, replaceable adapters
The client-facing tool contract should stay stable even if the backend changes. That way, you can move from one CRM vendor to another, or from a direct SQL query to an internal service, without retraining users or rewriting the whole client flow.
Trace everything that affects outcomes
Production incidents rarely start in one clean place. They come from a chain: the client picked a tool, passed weak context, the server retried a downstream call, and the result came back half right. Without traces and structured logs, root-cause work turns into guesswork.
A good MCP server should feel boring on a bad day. That is a compliment. It means the system is predictable when things go sideways.
Architecture diagrams
These three views are the ones we use most when we explain MCP projects to clients. First, the structure. Then the request flow. Then the trust boundaries. In our experience, that sequence helps both engineering teams and business stakeholders get to the same picture faster.
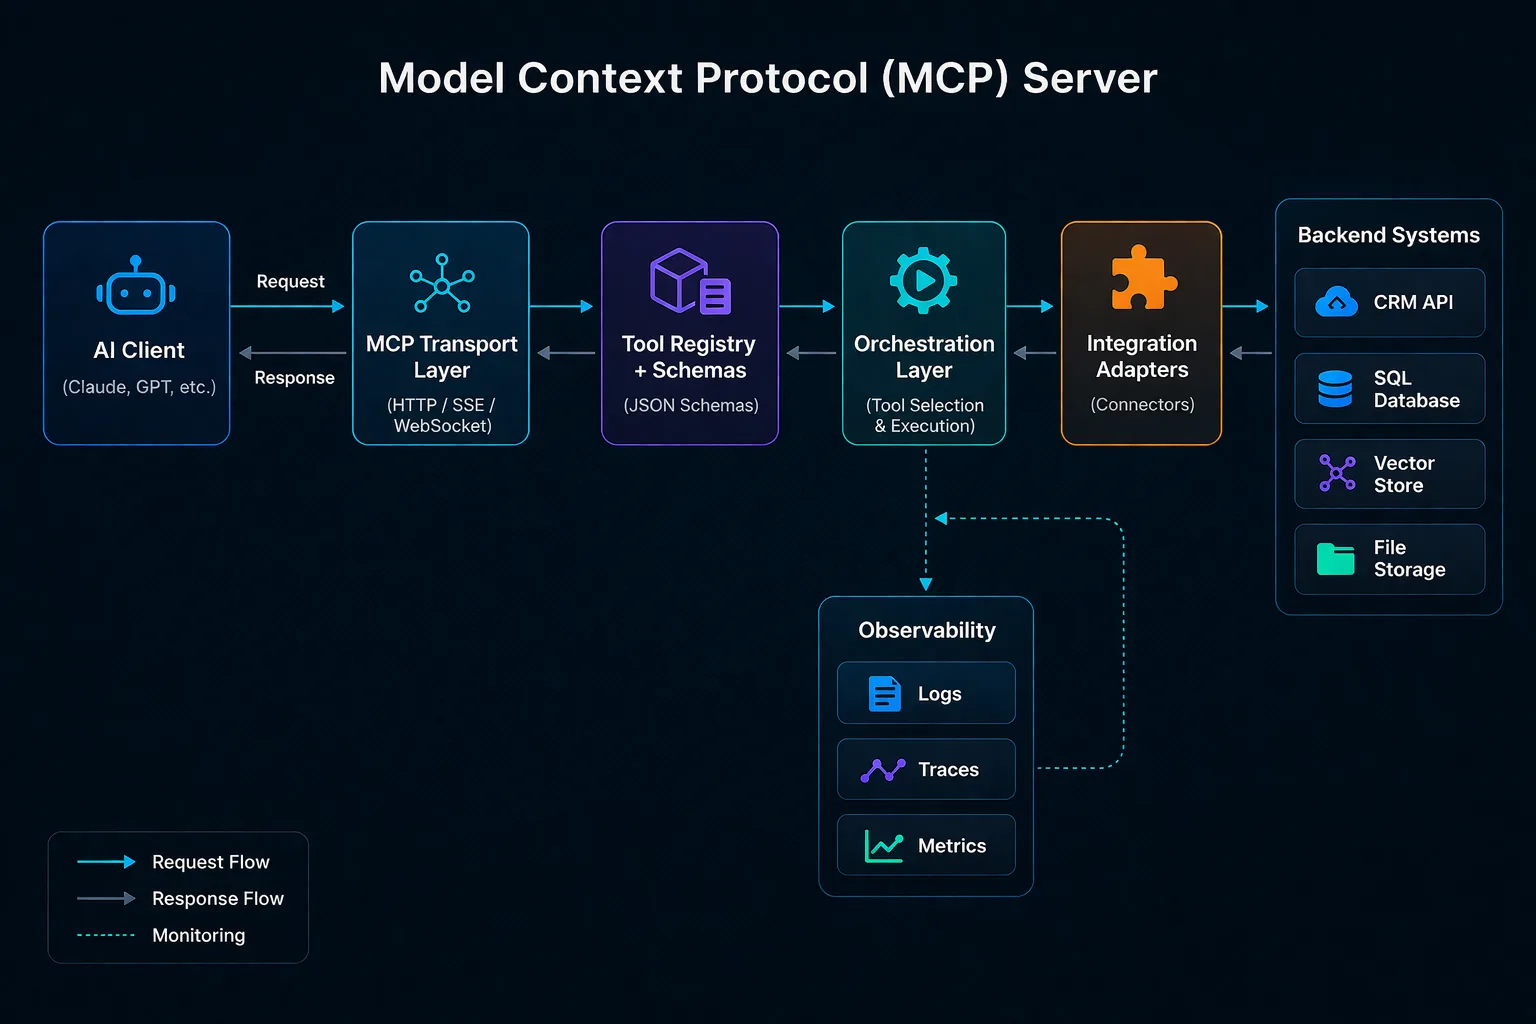
Diagram 1: high-level MCP architecture
High-level MCP architecture: the client talks to a protocol-facing transport, which resolves tools through schemas, invokes orchestration logic, and reaches backend systems through integration adapters. Logs, traces, and metrics sit beside execution from day one.
Tool call lifecycle
The lifecycle view shows that a tool call is not one quick backend jump. It is a controlled sequence: request interpretation, tool selection, validation, policy checks, downstream execution, normalization, and response.
Trust boundaries and security zones
The security view highlights the main production rule: trust should narrow as the request moves inward. Authentication, validation, authorization, logging, and output filtering are part of the architecture, not extras you add later.
Final point
MCP matters because it forces teams to be clear. Clear tool boundaries. Clear schemas. Clear permissions. Clear execution paths. That is what turns an agent system from a demo into something a real team can trust.
At Core Dynamics, that is what clients ask us for most once the first prototype hits real systems. Fewer surprises. Tighter boundaries. Better logs. Tools that keep working after the demo video is over. It is rarely about adding more tools. It is usually about making the right tools behave well.
If I had to boil it down to one rule, it would be this: keep the tool surface small, keep the policy layer strict, and keep the logs readable. Do that, and MCP stays useful. Skip it, and the architecture can look fine right up until it does not.